I have a PDF of multiple statements that I need to split by record. In DataMapper, I have set record bounderies by text “Page 1 of” and I am extracting a single field to use as the split PDF filename. My job preset passes this field to metadata at the Document level and my output preset seperates at Document level, generating thousands of PDF files to a location on our network. There is no template.
My process works splendidly, but since the source PDF was designed for print, some records contain a blank page at the end.
Is there any way in Datamapper, or the output preset, to remove blank pages from the split PDF files? Since they are for archiving and online access, a blank page in a digital file makes no sense.
Is there any predictable structure to when the blank pages appear? You say “some” and “at the end” but can that be narrowed down to something like “If the page count / number is odd, delete the last page”?
I’ll note that you don’t need Connect resources to do this job. You can use the PDF Splitter plugin in Workflow do to this.
The PDFEditObject (ppalambic) has a method to delete pages, but you have to know which pages to delete. There isn’t an “is this page blank” method to call. You could try to extract the text from the entire page area into a string then check the string… if you try something like this, you’d want to loop backwards through the PDF so that deleting a page doesn’t change the page count/loop counter.
Read up on the PDFEditObject’s properties and methods. There are example scripts on the forum that loop through a PDF and delete pages.
I’d personally take the approach of doing this all in script, but you can use Workflow plugins for a lot of this. Imagine a PDF Splitter outer loop and inner loop. The outer loops splits a new PDF on the text "Page 1 of " and also sets/scrapes whatever value to use for the final filename. The inner loop splits each page. Set the entire page contents into a variable (Set Job Infos and Variables plugin). Use a small script, set as a Condition, pass in that variable and check the string length. If it’s 0, set the script’s returnvalue to “false”, if not, set it to “true”. Then on the “true” branch do a “Send to Folder” with concatenation on (using the filename you generated/scraped before), to build a PDF that contains only non-blank pages. On the “false” branch, do a Delete.
The PDF is a statement run of credit union account statements. Some accounts are 2 pages, some are 20. The blank will always be the last page, but only if the last page with transactions is odd. It is the blank back of the last page.
Is the ppalambic not what powers the PP Image plugin? If so, then no thank you. We have had many issues with Workflow running out of available memory/storage during our busiest period on the first of the month. OL support has determined that the Image plug-in is to blame.
We print and mail account statements for many credit unions at the beginning of each month, and also create PDF archives of these mailings. To solve our memory issue, we have postponed the archiving processes (using PP Image) to begin running after hours, when we are not also generating Postscript files for print.
I am under the impression that Connect is much better at generating PDFs than Image is, and the memory issue will be resolved once I convert all these PlanetPress7 jobs to Connect, but i has been slow going.
For the issue at hand, can a JS script at the begining of my workflow process, before the PDF gets to the DataMapper, remove blank pages? Something like this:
// Load the PDF document
const pdfDoc = await PDFDocument.load(pdfBuffer);
const pages = pdfDoc.getPages();

// Track indices to delete (loop backward to preserve index order)
for (let i = pages.length - 1; i >= 0; i--) {
  const page = pages[i];

  // FIX: Lowercase "contents()" to properly check the stream
  const hasContent = page.node.contents() !== undefined;

  if (!hasContent) {
    pdfDoc.removePage(i);
  }
}

// Serialize the PDF to bytes
const pdfBytes = await pdfDoc.save();
return pdfBytes;
I got this from Gemini. It doesn’t work, but could it, if I knew how to edit the JavaScript?
Thanks for the tip about the PDFEditObject. I have concerns about the memory issues we’ve had in the past, but I can’t argue with the results.
Also, thanks Google Gemini for constantly refining my script.
var myPDF = Watch.GetPDFEditObject();
myPDF.Open(Watch.GetJobFileName(), false);
var myPDFPages = myPDF.Pages();

// Loop backward to safely delete pages
for (var j = myPDFPages.Count() - 1; j >= 0; j--) {
    var currentPage = myPDFPages(j);

    // Extract text from the page
    var pageTxt = currentPage.ExtractText2(0, 0, 8.5, 11);

    // Use a regular expression to test if the string is empty
    var isBlank = (/^\s*$/).test(pageTxt);

    Watch.Log("Checking page index " + j + ". Is Blank: " + isBlank, 2);

    if (isBlank) {
        // CRITICAL FIX: Release the reference to the page object before deleting it
        currentPage = null;
        CollectGarbage();

        myPDFPages.Delete(j);
        Watch.Log("Deleted blank page at index " + j, 2);
    } else {
        // Release reference even if we aren't deleting it to keep memory clean
        currentPage = null;
    }
}

// Explicitly nullify object variables to clear memory locks
myPDFPages = null;

CollectGarbage();
myPDF.Save(true);
myPDF.Close();
I am going to need to do this a lot as we convert PlanetPress jobs to Connect
Can anyone tell me why the Javascript above casues this error when added to a different Workflow process.
ERROR: 07:36:59.594 [0004] W3602 : Error 0 on line 34, column 1: AlambicEdit.AlambicEditPDF.1: Error saving PDF to ‘C:\ProgramData\Objectif Lune\PlanetPress Workflow 8\PlanetPress Watch\Spool\270.tmp\job010QVZDW938OCF361C0DE26.dat’: Expected a dict object.
**ERROR: 07:36:59.595 [0004] W3603 : Error running script: ** ERROR: 07:36:59.595 [0004] Run Script: W1603 : Plugin failed - 07:36:59 (elapsed time: 00:00:07.676)
The blank pages were NOT removed from the PDFs.
What is a “dict” object, and why is it expected in this process and not the previous process?
*****EDIT
Further tinkering has also produced this error
ERROR: 12:10:55.844 [0005] W3602 : Error 0 on line 29, column 9: AlambicEdit.AlambicEditPDF.1: Error deleting page 115: One or more pages are in use and could not be deleted.
**ERROR: 12:10:55.844 [0005] W3603 : Error running script: ** ERROR: 12:10:55.845 [0005] Run Script: W1603 : Plugin failed - 12:10:55 (elapsed time: 00:00:07.285)
The original Javascript still works fine in the original process. I do not see any reason it would not work with every process.
I think I saw somewhere that JScript had an issue with ppAlambic object references. Not sure?
But let’s try this in VBScript instead:
Dim myPDF : Set myPDF = Watch.GetPDFEditObject
Dim i
Dim pageText

myPDF.Open Watch.GetJobFilename, False
For i = myPDF.Pages.Count - 1 To 0 Step -1
   pageText = Trim(myPDF.Pages(i).ExtractText2(0,0,8.5,11))
   If Len(pageText) = 0 Then
        myPDF.Pages.Delete i
   End If
Next

myPDF.Save True
myPDF.Close
Set myPDF = Nothing
EDIT:
This JScript version of the VBS code above works for me:
var myPDF = Watch.GetPDFEditObject();
var pageText;
var isBlank;
//var j;

myPDF.Open(Watch.GetJobFileName(), false);

for (var j = myPDF.Pages().Count() - 1; j >= 0; j--)
{
    // Extract text from the page
    pageTxt = myPDF.Pages().Item(j).ExtractText2(0, 0, 8.5, 11);
    CollectGarbage();

    isBlank = (/^\s*$/).test(pageTxt);

    Watch.Log("Checking page index " + j + ". Is Blank: " + isBlank, 2);

    if (isBlank)
    {
      myPDF.Pages().Delete(j);
      Watch.Log("Deleted blank page at index " + j, 2);
    }
}

myPDF.Save(true);
myPDF.Close();
myPDF = null;

CollectGarbage();
Thank you for your response, but this script in VB gives me a familiar error.
ERROR: 14:26:54.204 [0004] W3602 : Error 0 on line 13, column 1: AlambicEdit.AlambicEditPDF.1: Error saving PDF to ‘C:\ProgramData\Objectif Lune\PlanetPress Workflow 8\PlanetPress Watch\Spool\270.tmp\job010QW2IVQTXDOAE63382699.dat’: Expected a dict object.
**ERROR: 14:26:54.205 [0004] W3603 : Error running script: ** ERROR: 14:26:54.205 [0004] Run Script: W1603 : Plugin failed - 14:26:54 (elapsed time: 00:00:07.705)
Google has told me the “dict” object is something about the internal structure of the PDF being corrupted. But the PDF was originally generated by Connect. Is there something in the Output Preset I need to examine?
Also, why does my original Javascript work in one process but not the other? Is file size a factor? The errors are generated when processing a much bigger file.
Also also, what happens to these scripts in VB when Microsoft no longer supports VB?
I have tested both VB and JScript versions and they work against my test files. If you’re experiencing errors it is most likely an issue with the underlying PDF. If it’s output from Connect I think you could legitimately open a support ticket to find out why the script is failing on that PDF.
If I understand your situation, you are producing PDFs out of Connect. The output contains blank pages where necessary for duplexing. Those blank pages are their own Print Section. You also want output that is separated by document, but without blank pages.
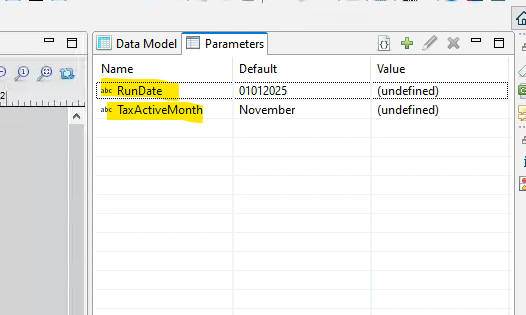
If my understanding is correct, you can put a Condition on the “Blanks” Print Section, to Show or Hide based on a Parameter. In Workflow, you have one branch were the Parameter contains a “true” or “show blanks” value, with a consolidated (single PDF) Create Output task.
On a different branch, change the Parameter to whatever value means “do not output blanks”, and have an Output Preset that Separates by Document.
You’ll have one output suitable for printing, and another output set suitable for archiving.
These parameters you speak of, they would be in the Workflow process?
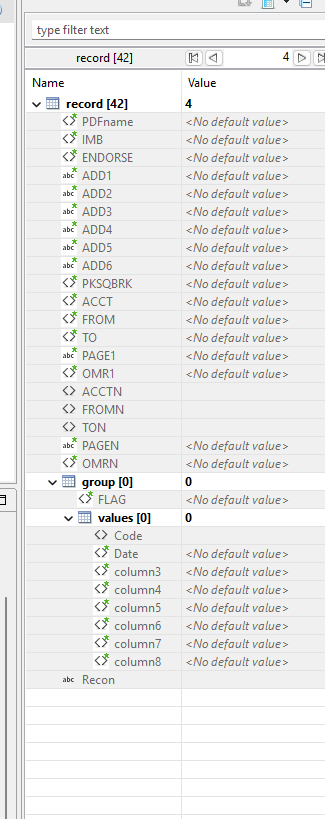
I am using a Control Script to generate the blank section based on empty fields. If there was a way to just not generate that section in a branch in Workflow, that would solve my problem.
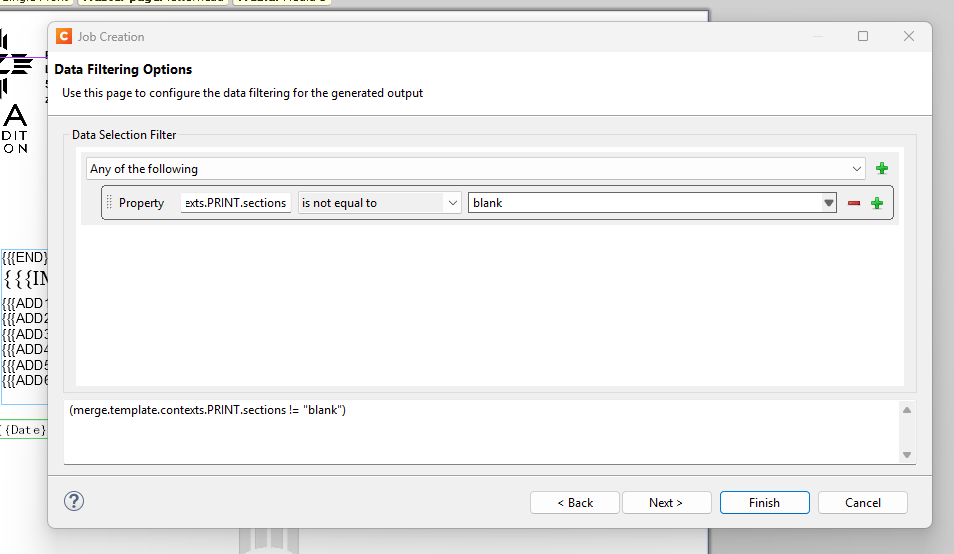
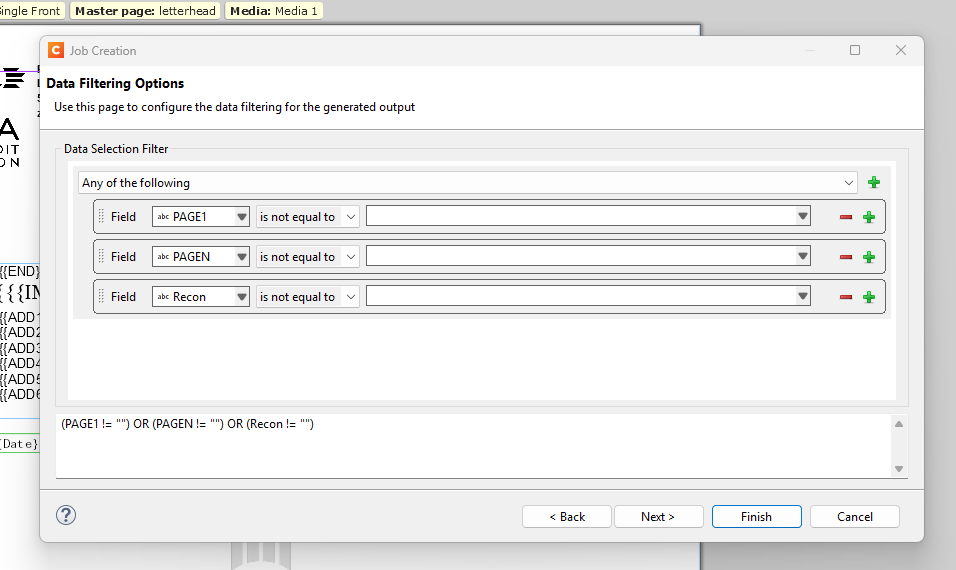
I have been working with OL Support to use the filtering option in a Job Preset, using the same fileds I use in the Control Script, but that, too, does not work, though it should.
SOME of the fields above are empty, but the ones I am testing say . I don’t know what I did differently, or how to set an empty default value. This project has been a real headache.
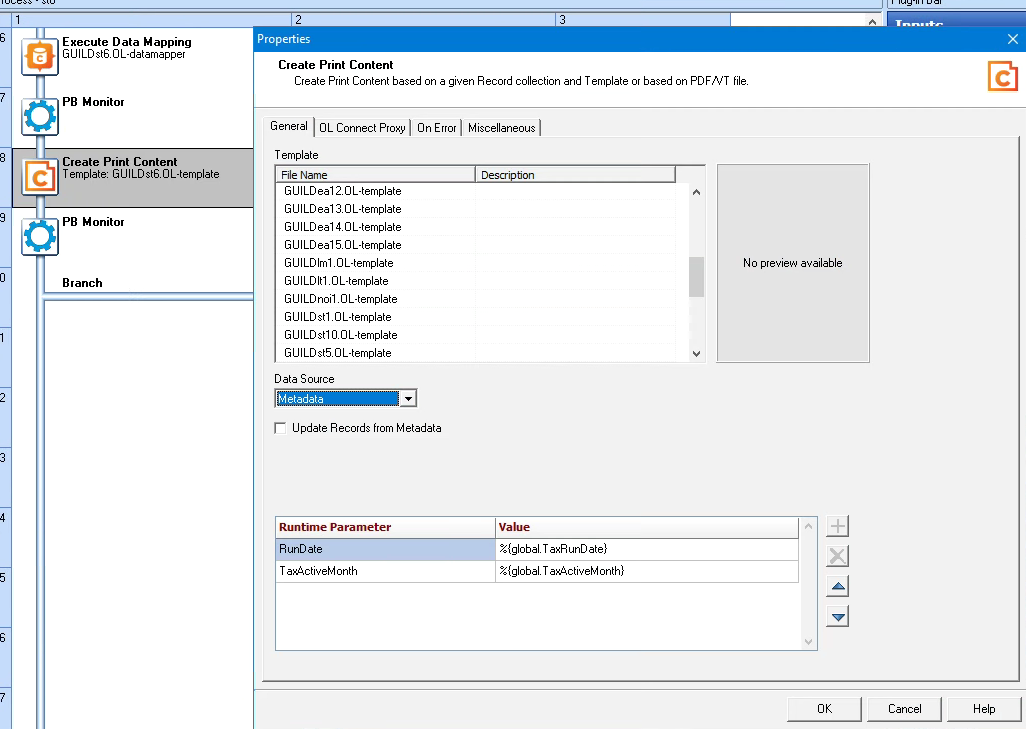
Whatever you define here, will appear in the Create Print Content Plugin, where you can supply them a value. Those values will be available in the Template, at runtime (thus “Runtime Parameters”). You can use them in scripting in the Template, including within Conditions.
Hopefully this gives you context for my previous post! Indeed, you can have your “blank” Print Section be conditional based on variables you define in the template and set at runtime, from Workflow.